Table of contents
Get a personalized demo of Stuut and see how it can help with AR automation.
Why warehouse integration is useful
Every AR record in Stuut arrives through either a bespoke ERP connector pulled over an API, or the customer uploads files on a schedule. Customers increasingly have a third option sitting in their stack already. Their invoices, payments, and customers live in a warehouse, refreshed by pipelines they already run. The warehouse can share tables with another account without copying anything. We built a channel where the warehouse itself is the integration, thus reducing the work on our customer’s IT and data teams to get Stuut up and running. This post covers what the customer builds, what Stuut reads, and the design choices that keep the new surface small and the data trustworthy.
How a share becomes an integration
The customer only does the setup work once. They create one secure view per AR entity, shaped to a previously agreed-upon contract: CUSTOMERS, CONTACTS, INVOICES, INVOICE_LINES, PAYMENTS, and PAYMENT_ALLOCATIONS. Each view has fixed column names and types, a stable key that is never reused, and a modified_at column that updates on any change to the row. We hand them a SQL template per view with placeholders, so they fill in their own column names and write no other SQL. They grant the views to a share and add Stuut’s account as a consumer.
On our side the share mounts as a read-only database inside Stuut’s own Snowflake account. Queries against it read the customer’s live tables. No export runs on the customer side. Queries against a share run on the consumer’s warehouse, so Stuut pays for sync compute and the customer pays nothing beyond the storage they already had.
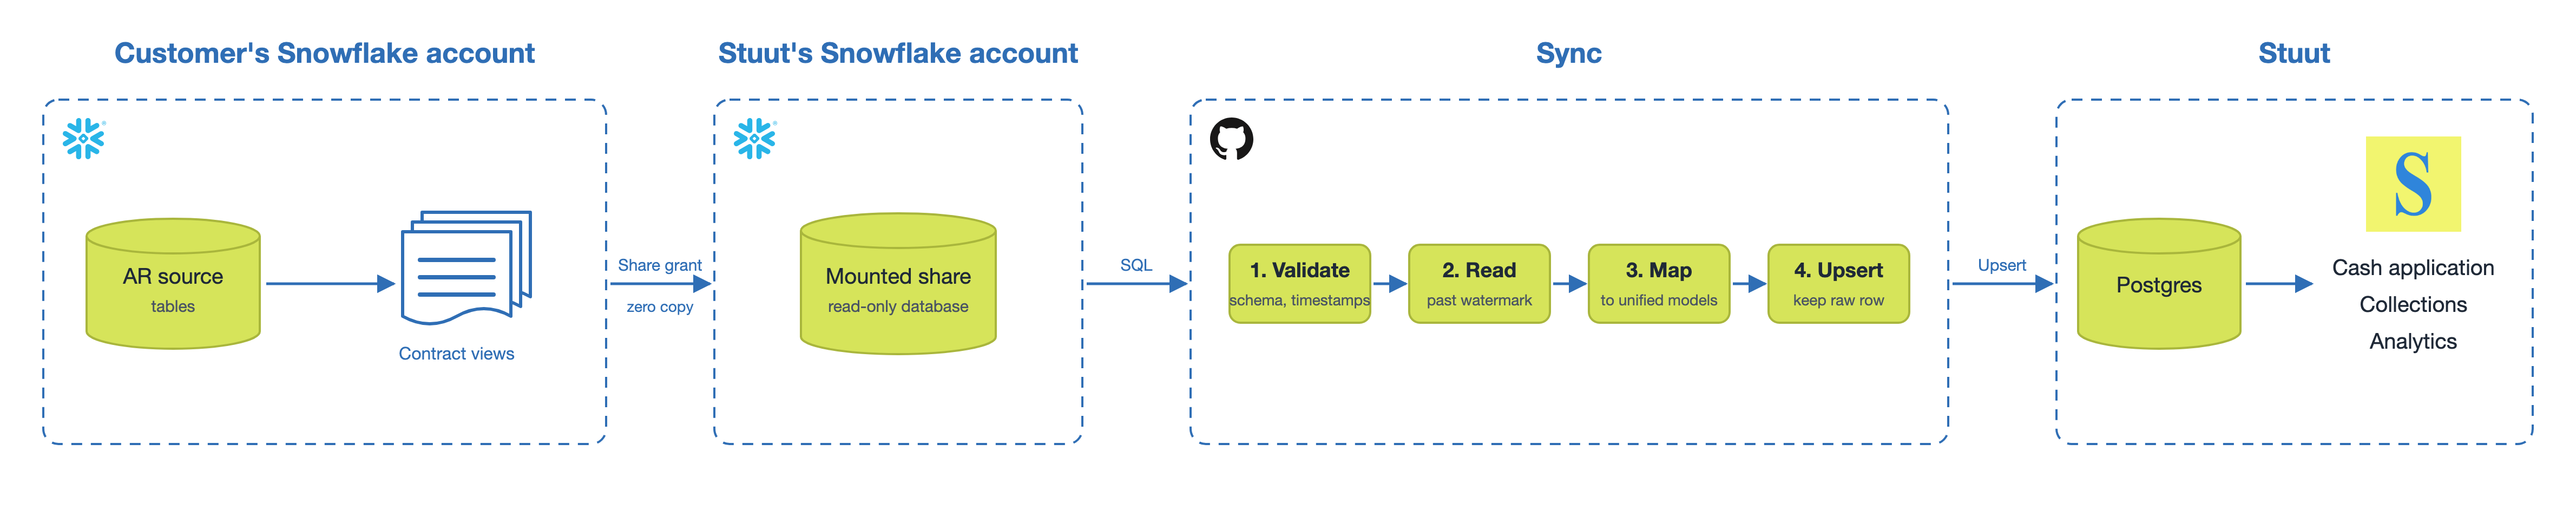
A sync run validates the share against the pinned contract version, then reads rows with modified_at newer than the last watermark in key-ordered pages of 5,000 that can resume mid-run. It maps each row to the unified models every connector produces, and upserts into Postgres on the integration and remote id, keeping the full original row on record for replay and data quality checks. Re-syncing the same rows updates them in place, which is what makes scheduled re-reads safe. Cash application, collections, and analytics downstream see the same integration data as any other connector.
Where the data can come from
A direct share works when the customer’s Snowflake account is in the same region as ours. Cross-region customers use a private listing, which Snowflake replicates into our region on a schedule. Customers on another warehouse can share too. For example, Snowflake mounts a Databricks Delta Share as a database, and the connector reads it like any other mount.
The integration is currently onboarding its first customers. Our FDE team takes each new share from grant to first sync, validating the mount against the contract before any rows move. After that first sync there is no further setup on the customer’s side, and scheduled syncs keep Stuut current with the warehouse.
Sharing runs the other way as well. A customer can receive their own Stuut data in their Snowflake account through a per-customer share of Stuut’s warehouse tables, filtered to their organization. Just like inbound sharing, nothing is copied and no credentials are shared.
Design decisions
The connector runs on the same v2 engine as our ERP integrations, so scheduling, retries, watermarks, and run logs come with it. The only new behavior is SQL against a mounted database instead of HTTP calls.
Every customer builds to the same published contract, with fixed view names, columns, and types which means one mapping serves all of them. When a mapping changes, Stuut changes it once.
The customer grants a share and Stuut logs into its own Snowflake with one service user, so there are no customer credentials to collect, store, or rotate. Revoking access is one statement on their side.
The customer owns the views and can change them without a Stuut deploy, so the sync checks the contract on every run.
- The modified_at column must be timezone-aware. A local-time value compared to a UTC watermark is skipped with no error, so the health check rejects naive columns.
- Views expose full tables and Stuut applies time filters at read time.
- Every money column carries a currency. Stuut never assumes USD.
- Deletes arrive as status changes. Rows that vanish are soft-flagged, never hard deleted.
- Failures name the row and the fields, never the values.
- Extra columns become custom fields, with the column COMMENT as the description. Added, removed, or retyped columns alert the FDE team once.